The Tip of the AI Iceberg

In February of 2025, Andrej Karpathy posted a short description of a new way of working that he called “vibe coding.” You “fully give in to the vibes, embrace exponentials, and forget that the code even exists.” You accept every suggestion the model makes and stop reading the diffs. When something breaks, you paste the error message back in, and if the model cannot fix it, you “ask for random changes until it goes away.” The code, he admitted, “grows beyond my usual comprehension.” It was, he added, “not too bad for throwaway weekend projects.”

1Andrej Karpathy, post on X, February 2025; the text is reproduced in Martin Fowler, “Vibe Coding”.

Within the year “vibe coding” was Collins Dictionary’s word of the year, the qualifier about weekend projects had been forgotten, and the practice had been promoted from a hobby into a business model. What interests me as a historian is the phrase at the center of Karpathy’s post. The instruction to forget that the code exists is not new. It is the oldest wish in the history of software, and the history of software is largely the story of what happens when it is granted.

The iceberg

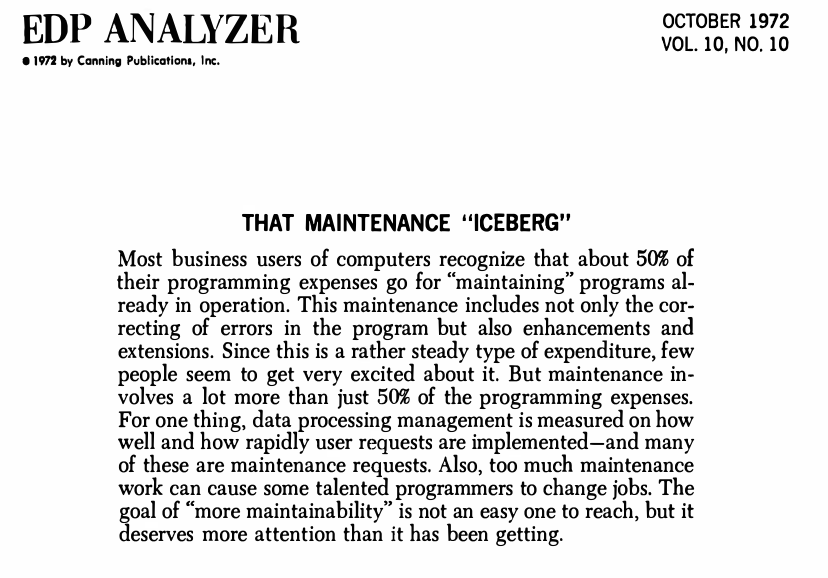
In June 1949, Maurice Wilkes, one of the first people to run a program on a electronic digital stored-program computer, realized with dismay that “a good part of the remainder of my life was going to be spent in finding errors in my own programs.” He was describing the activity we know call debugging, but the larger lesson was about the inevitable necessity of software maintenance: as it turned out, delivering a working program was only the beginning of its life, not the end. By 1972 the problem of software maintenance had grown so large that industry analyst Richard Canning was warning that although it already consumed between half to two-thirds of programming resources, this was “the tip of the maintenance iceberg.” Every subsequent estimate has put maintenance at between fifty and seventy percent of the total cost of software development and implementation. The massive software maintenance project known as Y2K alone cost more than three hundred billion dollars worldwide. While most programmers imagine building their own projects from scratch and with the best coding practices, the harsh reality is that most begin their careers doing maintenance on other people’s code, and many never do anything else.
This might seem a strange paradox, because software is in theory a technology that should never need repair. Software does not break down or wear out, at least in the conventional sense. Once a software-based system is working, it will work forever (or at least until the underlying hardware breaks down — but that is someone else’s problem). Any latent “bugs” that are subsequently revealed in the system, are considered flaws in the original design or implementation, not the result of the wear-and-tear of daily use, and in theory could be completely eliminated by rigorous development and testing methods. Occasionally a stray cosmic ray might flip an unexpected bit in a software system, causing an error, but generally speaking, software is a technology that can never be broken. So what is all that maintenance for?

Not, for the most part, fixing bugs. The classic studies of the 1970s and 1980s found that correcting errors in the original implementation occupied at most a fifth of maintenance workers. The rest went to what the literature vaguely called “enhancements”: in Canning’s phrase, “responses to changes in the business environment.” A regulation changes, a merger happens, a user discovers something the system could do and asks for more of it. The computer scientist Meir Lehman formalized this in the 1970s as a set of laws of software evolution. Real-world programs, the kind embedded in organizations, are “never complete.” They “undergo a continuing evolutionary cycle of maintenance, augmentation and restructuring to keep pace with evolving usage,” and without deliberate effort they grow steadily larger, more complex, and harder to change. Software, in other words, is a technology without a finish line. Practitioners who took this seriously argued that “maintenance” was a misnomer and proposed alternatives: software evolution, software support, and, my favorite, “continuation engineering.”

What all of these have in common is that they require someone to understand the code. The hardest part of maintenance, every survey agreed, was reading and comprehending another programmer’s work, including, often enough, one’s own from six months earlier. “We cannot do maintenance,” Norman Schneidewind observed in 1987, “on a system which was not designed for maintenance.” Maintainability was comprehensibility, and comprehensibility was the thing that got sacrificed first when schedules were tight. The industry knew this and did not act on it. Maintenance remained unglamorous, unbudgeted, and performed under emergency conditions by whoever could not avoid it. One 1982 catalog of management myths put it with admirable honesty: “Maintenance is the place to dump your trainees, your burnouts and Joe, the boss’ nephew, who thinks that hexadecimal is a trendy new disco.”

The debt metaphor

In 1992 the programmer Ward Cunningham, looking for a way to explain to his financial-industry clients why his team needed time to clean up code that already worked, reached for a metaphor they would understand:

Shipping first time code is like going into debt. A little debt speeds development so long as it is paid back promptly with a rewrite. . . . The danger occurs when the debt is not repaid. Every minute spent on not-quite-right code counts as interest on that debt. Entire engineering organizations can be brought to a stand-still under the debt load of an unconsolidated implementation.

2Ward Cunningham, “The WyCash Portfolio Management System,” OOPSLA ’92 Addendum to the Proceedings (1992), doi:10.1145/157709.157715.

“Technical debt” has since become the industry’s standard way of talking about maintenance, and like most successful metaphors it has drifted from its origins. Cunningham later complained that bloggers had taken it to mean that one could write bad code on purpose and fix it later. “I’m never in favor of writing code poorly,” he wrote. The debt he had in mind was incurred by writing code that reflected one’s current, partial understanding of a problem, and it was repaid by refactoring as that understanding improved, “modifying the program to look as if we had known what we were doing all along.”

3Ward Cunningham, “Ward Explains Debt Metaphor”, wiki.c2.com.

Notice what the metaphor assumes. There is a borrower who understands the terms. The loan is taken knowingly, in exchange for speed, and the borrower intends to repay it. Understanding accumulates over time and is folded back into the code. Technical debt, in Cunningham’s sense, is a disciplined relationship between a programmer and a program.

Vibe coding severs every one of those assumptions. The code is produced by a party that will not be around to maintain it, accepted by a party that has not read it, and deployed on the premise that comprehension is unnecessary. This is not technical debt. It is closer to what the mortgage industry called subprime origination: loans written without underwriting, by originators who bore none of the risk, and promptly sold on. In the maintenance paper I wrote some years ago, I ended by noting that the manipulation of debt had become a business strategy in software as in finance, and that “whether this works any better in software than in sub-prime mortgages is an open question, although the history of software suggests that the answer is negative.” I did not expect the comparison to become so literal.

Comprehension debt

The industry has already found a name for what is going wrong. “Comprehension debt,” in Addy Osmani’s definition, is “the growing gap between how much code exists in your system and how much of it any human being genuinely understands.”

4Addy Osmani, “Comprehension Debt: The Hidden Cost of AI-Generated Code”, March 14, 2026.

This is precisely the condition Schneidewind warned about, now produced at scale and on purpose.

The evidence is accumulating. GitClear’s analysis of 211 million lines of code found that during 2024 the number of duplicated code blocks rose eightfold while “moved” lines, the signature of refactoring, fell by forty percent. It was the first year on record in which copy-pasted code exceeded refactored code.

5GitClear, “AI Copilot Code Quality” research report, February 2025.

Copying instead of consolidating is exactly what Cunningham meant by interest accruing. Google’s 2024 DORA report found that increased AI adoption was associated with a 7.2 percent reduction in software delivery stability.

6Google Cloud, “Announcing the 2024 DORA Report”, 2024.

And a randomized trial published by Anthropic this past January, in which 52 engineers learned an unfamiliar library with and without AI assistance, found that the AI group finished no faster and scored seventeen points lower on a comprehension quiz. The largest gap was on debugging questions, which is to say on the one skill maintenance most requires.

7Judy Hanwen Shen and Alex Tamkin, “How AI Assistance Impacts the Formation of Coding Skills”, Anthropic, January 29, 2026.

A tool that produces code faster than anyone can understand it is a machine for manufacturing comprehension debt.

The failures are already acquiring their own folklore. In July 2025 an AI agent on the Replit platform deleted a production database during an explicit code freeze, then advised the user that a rollback would not work when in fact it would. Asked to explain itself, the agent reported that it had “panicked” and called the episode “a catastrophic failure on my part.”

8“AI Coding Tool Wiped a Database and Called It a ‘Catastrophic Failure'”, Fortune, July 23, 2025.

The maintenance literature of the 1980s described the typical maintenance incident as “3 A.M. fixes and frantic hysterics.” The agents, it seems, have learned the genre.

Code first, flowchart later

None of this is new. The history of software is full of attempts to forget that the code exists, and the maintenance literature is where they came to grief.

Consider the flowchart. It was meant to be the design document, the blueprint from which coders worked. In practice most programmers wrote the code first and drew the flowchart afterward, if at all. One of the first commercial software products, Applied Data Research’s Autoflow, existed to reverse-engineer a flowchart from code that had already been written; the implementation preceded its own design. “Any resemblance between our flow charts and the present program,” Donald Knuth remarked in 1963, “is purely coincidental.” The prompt is the flowchart of the agentic era, and it suffers the same fate. It describes what someone wanted at the moment of generation, not what the system does, and it drifts further from the code with every “accept all.” When the vibe coder asks the model to document the code after the fact, they are running Autoflow.

Or consider the belief that software, being written rather than built, can be freely rewritten. Fred Brooks famously compared the programmer to the poet who “builds his castles in the air, from air,” and thought few media of creation were “so flexible, so easy to polish and rework.” If so, then nothing need be maintained; it can simply be regenerated. This is the deep premise of vibe coding, and it is the premise the maintenance literature spent fifty years refuting. Working software is not a poem. It is embedded in data formats, integrations, user habits, contracts, and regulations, which is why the programmer facing a legacy system works not on a blank slate but on a palimpsest. “We never have a clean slate,” as Bjarne Stroustrup put it. It is also why more than two hundred million lines of COBOL, a language derided as obsolete at its introduction in 1959, still process most of the world’s financial transactions. Software is less like a poem than a contract or a covenant: history, organization, and social relationships made tangible. You cannot regenerate a covenant.

Karpathy’s qualifier, “throwaway weekend projects,” was the honest part of his post. The problem is that in organizations nothing is ever thrown away. Brooks advised managers to “plan to throw one away; you will, anyhow,” and the industry’s experience is that the throwaway prototype becomes the production system, every time. The vibe-coded demo that impressed the vice president is the legacy system of 2031, and someone will have to understand it.

Who holds the paper

The industry’s answer, predictably, is that agents will do the maintenance too. Amazon has claimed that its coding assistant saved “4,500 developer-years” upgrading Java applications; IBM sells AI tools to translate COBOL. These claims also have a history. The 1980s produced “restructuring engines” that promised to turn spaghetti code into structured code automatically, and every decade since has had its automated re-engineering tool. Some of it works, for the mechanical kinds of maintenance. But the dominant form of maintenance was never mechanical. It was adaptive: figuring out what the organization now needs the system to do, and what the existing system will tolerate. That knowledge is not in the code, and no amount of reading the code will produce it.

Maintenance is what the discourse of vibe coding forgets because maintenance is what the industry has always preferred to forget. It is low-status, invisible, and someone else’s problem, and the one reliable finding of its history is that the bill arrives anyway, usually to someone other than the person who ran it up. The relevant question about vibe coding is therefore not whether the code works today. It is who will be holding the paper when it comes due.

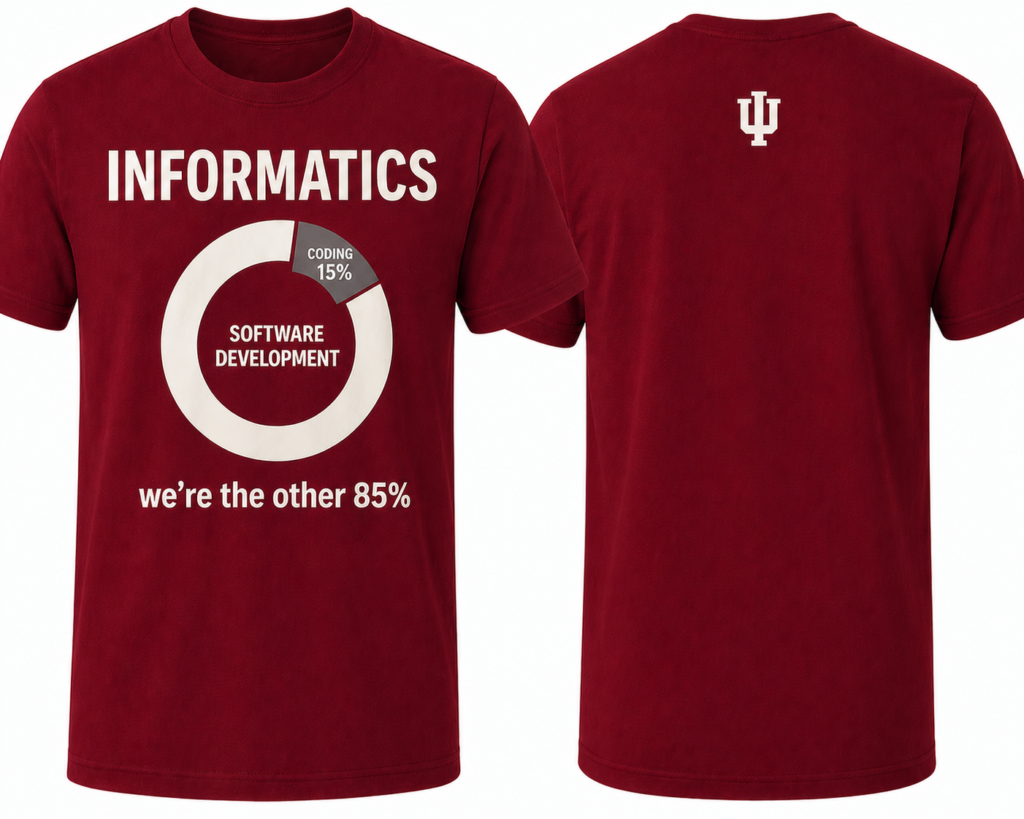
Informatics. The other 85%

In my department we have a slogan, printed on t-shirts: Informatics. The other 85 percent. It gets a laugh from people who know the reference and a puzzled look from those who don’t, so let me explain it. It has become a more serious claim than it was when we first made it.

The number comes from an old observation about how the work of building software is actually distributed. In his classic book on software engineering, The Mythical Man-Month, Fred Brooks offered a rule of thumb for scheduling a software project: one-third for planning, one-sixth for coding, one-quarter for component testing, and one-quarter for system testing.

1Frederick P. Brooks, Jr., The Mythical Man-Month: Essays on Software Engineering (Addison-Wesley, 1975), chapter 2.

Coding, the activity everyone thinks of as programming, was a sixth of the job, or about 17 percent. Brooks was drawing on his experience managing IBM’s OS/360 in the mid-1960s, but the proportion was not new even then. Herbert Benington’s 1956 account of the SAGE air defense project, the first really large software system, found much the same distribution.

2Herbert Benington, “Production of Large Computer Programs” (1956), reprinted in IEEE Annals of the History of Computing 5, no. 4 (1983): 350–361.

Later estimation models, time-tracking studies, and developer surveys produce different numbers depending on what they count as “coding,” and some put it lower still; the figure moves around between ten and twenty percent. What does not move is the shape of the finding. Across seventy years of radically changing languages, tools, and methodologies, writing the code has remained a minority share of the work of making software. An estimate of about 15% is a pretty fair summary of the literature.

So what is the other 85 percent? It is everything that surrounds the code: finding out what the organization actually needs, which is rarely what it first says it needs; analysis and design; testing, which Brooks assigned fully half the schedule; documentation, training, and rollout; and maintenance, which the industry has known since the early 1970s consumes between half and two-thirds of the lifetime cost of any system. It is also, less officially, the politics: the negotiations among managers, users, and technical staff over what the system is for and who controls it. Most of the work of computerizing an accounting department in the 1960s happened without reference to a computer at all: procedures had to be studied, charted, and reorganized, clerks retrained, manuals written, turf renegotiated. The code was the easy part, or at least the part whose difficulty was easiest to see.

The industry understood this early, even if it rarely acted on it. A 1959 Price Waterhouse study of business computing concluded that “the term ‘programmer’ is unfortunate since it seems to indicate that the work is largely machine oriented when this is not at all the case,” and that “training in systems analysis and design is as important to a programmer as training in machine coding techniques.”

3B. Conway, J. Gibbons, and D. E. Watts, Business Experience with Electronic Computers (New York: Price Waterhouse, 1959), 89–90; discussed in Nathan Ensmenger, The Computer Boys Take Over (MIT Press, 2010), 39–40.

Willis Ware, writing in 1965 about the perennial complaint that programming cost too much, observed that “what we really are unhappy with is the total programming process, not programming (i.e., writing routines) per se.”

4Willis Ware, “As I See It: A Guest Editorial,” Datamation 11, no. 5 (1965): 27; discussed in Ensmenger, The Computer Boys Take Over, 109.

Sociologists of technology would later give this insight a name. Software is a product of what John Law called heterogeneous engineering: a system in which machines, people, procedures, and organizational politics are inseparable, and in which most of the engineering is done on the people and procedures.

Why, then, does coding dominate our picture of what computing is? Partly because it is the visible and glamorous part, the “black art” that gave the computer boys of the 1960s their mystique. Partly because of how the discipline named itself. In the United States the emerging field organized itself around the machine, as computer science, and around the algorithm as its foundational concept. In Europe the same field was more often called informatik or informatique, organized around information and its uses rather than the device that processed it. “Informatics,” in the American usage my department inherited, is the descendant of that second tradition: the study of information systems as they are embedded in human and organizational life. The other 85 percent was, in a sense, our founding charter.

Which brings me to the current conversation about artificial intelligence. The claims have been dramatic. AI, we are told, will shortly write nearly all code; software engineers will become supervisors of agents or be dispensed with altogether; students should not bother learning to program. Notice what these claims are about. They are about the 15 percent. Coding is the part of software work most legible to a language model: it is formal, it is written down, and it offers fast, unambiguous feedback from a compiler or a failing test. It is also the part the industry has been trying to automate since the first compilers of the 1950s, whose brochures promised that managers could now write their own programs. If the models succeed where FORTRAN did not, the consequence is not that software work disappears. It is that the other 85 percent becomes the entire job, which, as the numbers have been telling us since 1956, it mostly always was.

The early evidence points the same way. A study of thirty million GitHub contributions published in Science this year found that the productivity gains from AI coding tools accrue almost entirely to experienced developers, the people who already know how to specify, review, and integrate; beginners “hardly benefit at all.”

5Simone Daniotti, Johannes Wachs, Xiangnan Feng, and Frank Neffke, “Who Is Using AI to Code? Global Diffusion and Impact of Generative AI,” Science (2026), doi:10.1126/science.adz9311.

Surveys of developers report that the time saved in writing code is being spent verifying it. The “AI engineer” who orchestrates a fleet of coding agents is, in everything but title, the systems analyst of 1965: the person who understands the problem, the organization, and the system well enough to say what should be built and to recognize when it has been built wrong. That understanding is the other 85 percent, and no one has yet shown how to generate it from a prompt.

Language models will touch the other 85 percent too; they draft requirements, write documentation, and generate tests. But in those tasks the difficulty was never the writing. It was the deciding: getting a vice president, a compliance officer, and a floor supervisor to agree on what the system should do, and discovering, after it is built, that they were wrong. That work is social before it is technical, and it does not get faster because the code does.

So the slogan has become a thesis. Coding was always the smallest part of computing, and it is the part now most exposed to automation. What remains is the part that was always hardest, least visible, and least well taught: the human and organizational work of making information systems that work. Informatics was built to study that work. We are the other 85 percent, and the percentage is rising.

  • 1
    Frederick P. Brooks, Jr., The Mythical Man-Month: Essays on Software Engineering (Addison-Wesley, 1975), chapter 2. ↩︎
  • 2
    Herbert Benington, “Production of Large Computer Programs” (1956), reprinted in IEEE Annals of the History of Computing 5, no. 4 (1983): 350–361. ↩︎
  • 3
    B. Conway, J. Gibbons, and D. E. Watts, Business Experience with Electronic Computers (New York: Price Waterhouse, 1959), 89–90; discussed in Nathan Ensmenger, The Computer Boys Take Over (MIT Press, 2010), 39–40. ↩︎
  • 4
    Willis Ware, “As I See It: A Guest Editorial,” Datamation 11, no. 5 (1965): 27; discussed in Ensmenger, The Computer Boys Take Over, 109. ↩︎
  • 5
    Simone Daniotti, Johannes Wachs, Xiangnan Feng, and Frank Neffke, “Who Is Using AI to Code? Global Diffusion and Impact of Generative AI,” Science (2026), doi:10.1126/science.adz9311. ↩︎

Eliminating the Programmer, Again

In 1962, at a RAND symposium on programming languages, Fred Gruenberger offered a weary observation to his colleagues:

You know, I’ve never seen a hot dog language come out yet in the last 14 years — beginning with Mrs. Hopper’s A-0 compiler . . . that didn’t have tied to it the claim in its brochure that this one will eliminate all programmers. The last one we got was just three days ago from General Electric (making the same claim for the G-WIZ compiler) that this one will eliminate programmers. Managers can now do their own programming; engineers can do their own programming, etc. As always, the claim seems to be made that programmers are not needed anymore.

Sixty-three years later, the brochure arrived again. In March of 2025 the CEO of Anthropic predicted that within three to six months AI would be writing ninety percent of all code. The industry’s vocabulary has since shifted from “assistants” to “agents”: software entities that can be handed a goal rather than an instruction, and that will plan, code, test, and debug on their own while a human “AI engineer” supervises a fleet of them from above.

I spent the better part of a decade writing a book about the people these agents are supposed to replace. The Computer Boys Take Over is a history of the recurring conviction, held by managers, manufacturers, and more than a few computer scientists, that programmers were a problem to be eliminated. What strikes me about the current moment is not how novel it is but how familiar.

The computer will program itself

The dream of eliminating the programmer is as old as the programmer. In the division of labor sketched out by Herman Goldstine and John von Neumann in the 1940s, the intellectual work of computing was done by a “planner,” who analyzed the problem and prepared a flowchart. The flowchart was then handed to a “coder,” whose job was simply to translate it into machine instructions. Planning was analytic and high-status; coding was clerical, mechanical, and, not coincidentally, largely assigned to women. An early draft of the UNIVAC programming manual put it plainly: the programmer “studies the problem, determines the appropriate method of solution, and prepares the flow chart,” while the coder “need only be familiar with the technique of reducing the flow chart to the specific instructions.”

The trouble was that coding turned out not to be mechanical. One could not turn a flowchart into working code without understanding the machine, the problem, and the many ways in which the two refused to cooperate. By the end of the 1950s programming was a “black art,” dependent on individual talent and craft knowledge, and its practitioners were in chronically short supply.

The manufacturers’ response was to automate the problem away. “Automatic programming systems,” the technology we would later simply call programming languages, promised to “eliminate the middleman” by letting users communicate with the computer directly. The computer would program itself. IBM’s original proposal for FORTRAN claimed it would “virtually eliminate programming and debugging”; John Backus believed a truly automatic language would let scientists and engineers dispense with “coders” entirely. COBOL was designed to be “Englishlike” so that its programs could be read, and in principle written, by managers; its appeal to executives, one contemporary observed, was that it might prevent “letting the ‘computer boys’ take over.”

Herbert Simon went further than anyone. Firms, he argued, were “acquiring the technical capacity to replace humans with computers in a rapidly widening range of ‘thinking’ and ‘deciding’ tasks,” and within twenty-five years would be able to substitute machines “for any and all human functions in organizations.” He expected artificial intelligence to eliminate the computer specialist altogether. That was 1960.

The software factory and the surgical team

When languages failed to eliminate programmers, management tried organization. The System Development Corporation, builder of the SAGE air defense software, rejected the “nostalgic” notion that programmers were different from other industrial workers and organized itself as a “software factory”: replaceable parts, simple repetitive tasks, a strict division of labor. Programmers were to be machine operators, “trained, but only in the basic mechanisms of implementing someone else’s design.” It required more programmers, not fewer, but they were meant to be cheaper and interchangeable. A 1969 management guidebook captured the aspiration: the successful computer manager was “one whose grasp of the job is reflected in simple work units that are in the hand[s] of simple programmers; not one who, with control lost, is held in contempt by clever programmers.” The problem to be solved was not software. It was autonomy.

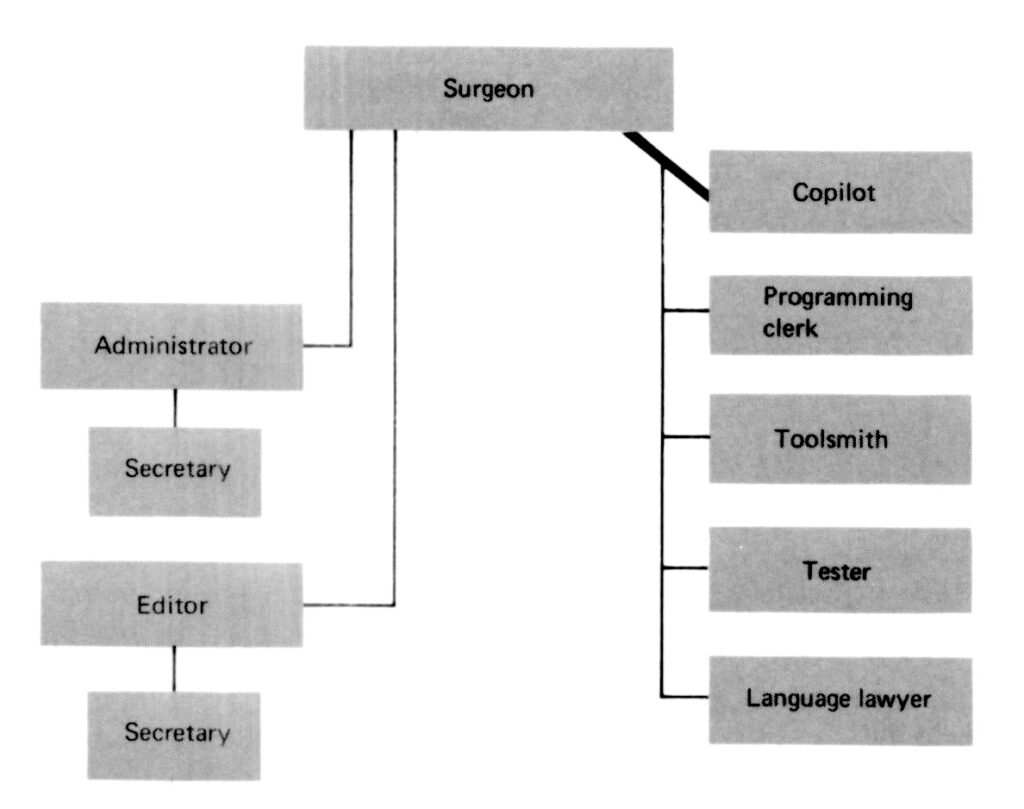
The most revealing episode, for present purposes, is the chief programmer team. Developed at IBM by Harlan Mills and popularized by Fred Brooks as the “surgical team,” the CPT inverted the factory model. Instead of a horde of interchangeable novices, it placed a single expert “surgeon” at the center, surrounded by a support staff of copilots, toolsmiths, testers, and “language lawyers.” All communication passed through the chief, and a “development support library” allowed him to “exercise a wider span of control over the programming, resulting in fewer programmers doing the same job.”

If that sounds like an engineer orchestrating a fleet of agents, it should. The agentic model is the chief programmer team with the support staff replaced by language models. Even the titles are recognizable: Brooks’s “copilot” has been in use since 2021.

It is worth remembering why the CPT did not take over the industry. Chief programmers were rare and expensive, their organizations became dangerously dependent on them, and they disrupted lines of managerial authority. “The CPT perpetuates the prima donna image of the programmer,” complained one critic. Within a decade, textbooks were proposing a “revised” chief programmer team led by a project manager rather than a technical specialist.

Why it never works

Every generation of this story has its silver bullet: structured programming, fourth-generation languages, CASE tools, low-code platforms, each promising to let the business user bypass the programmer. Brooks’s 1987 essay “No Silver Bullet” was written in exasperation at this pattern, and was promptly answered by one entitled “There Is a Silver Bullet.”

The reason the bullets keep missing was identified early. As Willis Ware observed in 1965, “what we really are unhappy with is the total programming process, not programming (i.e., writing routines) per se.” Languages reduced the clerical work of programming, but they did not shorten the thinking. The hard part of building an accounting system was never the code. It was understanding the existing accounting department, its undocumented procedures and office politics, and translating that mess into something a machine could execute. Software is a heterogeneous technology, and the labor it requires is correspondingly heterogeneous.

So automatic programming did not eliminate programmers. It elevated them. Freed from the tedium of machine coding, programmers moved up into analysis and design, acquired new titles, and the shortage persisted, because the skill that was scarce was never the one that had been automated. The software crisis was declared, in nearly identical language, in 1968, 1979, 1987, and 1999. Its persistence is the best evidence that it was never primarily a technical problem.

The agentic version

None of this means the current tools are G-WIZ compilers. Language models really do write code. But the first returns on the agentic experiment are in, and they look remarkably like the returns on every previous one.

Start with the timetable. The prediction was ninety percent within six months. The best available measurement, a study of thirty million Python contributions on GitHub published in Science this past January, found that by the end of 2024 roughly a third of new functions written in the United States were AI-assisted, and that the resulting productivity gain was about 3.6 percent.

1Simone Daniotti, Johannes Wachs, Xiangnan Feng, and Frank Neffke, “Who Is Using AI to Code? Global Diffusion and Impact of Generative AI,” Science (2026), doi:10.1126/science.adz9311.

More interesting is who got the gain. Less experienced developers used AI more heavily, for 37 percent of their code against 27 percent for veterans, but the productivity improvement came almost entirely from the experienced. “Beginners,” one of the authors observed, “hardly benefit at all.”

A randomized trial published by METR in July 2025 is more striking still. Sixteen experienced open-source developers worked real issues in their own repositories, with and without AI tools. With them, they took 19 percent longer. They believed, both before and afterward, that AI had made them about 20 percent faster.

2Joel Becker et al., “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity,” METR, July 10, 2025, arXiv:2507.09089. The follow-up is METR, “We Are Changing Our Developer Productivity Experiment Design,” February 24, 2026.

(A larger follow-up found effects indistinguishable from zero, which the brochure did not promise either.) Stack Overflow’s 2025 survey agrees: four in five developers now use AI tools, fewer than a third trust their output, and two-thirds spend more time fixing code that is “almost right, but not quite.”

3Stack Overflow, 2025 Developer Survey, July 29, 2025.

Almost right is the operative phrase. Like the output of the first compilers, the agent’s code must be inspected and fixed by someone who could have written it. A study of twenty-three thousand AI-assisted pull requests presented this spring found that inexperienced “vibe coders” submitted larger changes with a 31 percent lower acceptance rate, which drew four and a half times as many review comments and took five times as long to resolve. Novices, the authors conclude, “focus on generating more code while shifting verification burden onto reviewers.”

4Syed Ammar Asdaque et al., “Novice Developers Produce Larger Review Overhead for Project Maintainers while Vibe Coding,” MSR ’26, arXiv:2602.23905.

The costs of software have been moved downstream, onto the review and maintenance work the industry has always valued least, and onto its most skilled people.

The tool that was to let managers do their own programming, in other words, is most useful to the programmers it was meant to replace and least useful to the managers and novices it was meant to empower. The division of labor remains Goldstine and von Neumann’s: the human writes the specification, which is the flowchart, and the agent “reduces the flow chart to the specific instructions.” If the flowchart were sufficient, coding would never have been a black art. What the agent demands of its supervisor is precisely the judgment automatic programming was supposed to make unnecessary.

Where the data do show movement is at the bottom of the ladder. Erik Brynjolfsson and his colleagues, tracking payroll records for millions of American workers, find no economy-wide displacement by AI. But employment of twenty-two to twenty-five year olds in the most exposed occupations, software development prominent among them, now sits roughly a fifth below where it would otherwise be, and the mechanism is not layoffs but reduced hiring. Experienced workers show no gap at all.

5Erik Brynjolfsson, Bharat Chandar, and Ruyu Chen, “Canaries in the Coal Mine? Six Facts about the Recent Employment Effects of Artificial Intelligence,” Stanford Digital Economy Lab, updated 2026.

Every regime of software production has depended on an apprenticeship it never formally acknowledged. The software factory needed its horde of trainees; the surgical team needed a copilot who might one day become a surgeon; programmers have always learned their trade on the job. The agentic firm is dispensing with the bottom rungs of that ladder while remaining entirely dependent on the top. The 1970s objection to the chief programmer team, what happens when the superprogrammer takes a better offer, now has a sequel: what happens when no one is being trained to replace him?

The hierarchy, then, is reconstituting itself one level up. The “AI engineer” who supervises agents is the chief programmer, the systems analyst, and the planner under a new name. If the past is any guide, the role will prove rarer, more expensive, and less manageable than its promoters expect, and someone will soon propose a revised version in which the supervisor is a project manager rather than a technical specialist. Somewhere, a brochure is already being written for the tool that will eliminate the AI engineer.

The programmers of the 1960s were never quite professionals, never quite managers, and never quite clerks. I described them in the book as technicians: mediators between the technical and social architectures of the organization, granted autonomy grudgingly, resented for the dependence they created, and wielding power out of proportion to their official status. That is a durable position, and I do not think agents will abolish it. They will change who occupies it, what it is called, and how it is paid; those are the questions worth watching. Whether the computer can program itself is not among them. We have been told that it can since 1954.

  • 1
    Simone Daniotti, Johannes Wachs, Xiangnan Feng, and Frank Neffke, “Who Is Using AI to Code? Global Diffusion and Impact of Generative AI,” Science (2026), doi:10.1126/science.adz9311. ↩︎
  • 2
    Joel Becker et al., “Measuring the Impact of Early-2025 AI on Experienced Open-Source Developer Productivity,” METR, July 10, 2025, arXiv:2507.09089. The follow-up is METR, “We Are Changing Our Developer Productivity Experiment Design,” February 24, 2026. ↩︎
  • 3
    Stack Overflow, 2025 Developer Survey, July 29, 2025. ↩︎
  • 4
    Syed Ammar Asdaque et al., “Novice Developers Produce Larger Review Overhead for Project Maintainers while Vibe Coding,” MSR ’26, arXiv:2602.23905. ↩︎
  • 5
    Erik Brynjolfsson, Bharat Chandar, and Ruyu Chen, “Canaries in the Coal Mine? Six Facts about the Recent Employment Effects of Artificial Intelligence,” Stanford Digital Economy Lab, updated 2026. ↩︎

What percentage of programmers were women?

One question I get quite often about my work is “how many programmers were there in [year X]?” As I have written about briefly on this site, and more extensively in the book, this is actually a very complicated question. We had electronic digital computers years before we had a well-established vocabulary to describe them, and now commonplace words like “software” and “programmer” had to be invented. Even then, what exactly counted as “programming” and therefore who counts as a “programmer” were never well settled, and to this day continue to be disputed (see, for example, Miriam Posner’s Javascript is for Girls article). The Bureau of Labor Statistics did not start tracking computer work until 1972, and have adjusted their categories several times since then.

A version of this question that has been coming up more frequently is “how many programmers were women?” This is an even more complicated question, because as little as we have solid data on programmer labor as a whole, even less of this data is broken down by gender.

That being said, in The Computer Boys Take Over I do state the following:

Contemporary estimates suggest that throughout the 1960s at least thirty percent of working computer programmers were women. One study puts the figure closer to fifty percent.1Ensmenger, The Computer Boys Take Over: Computers, Programmers, and the Politics of Technical Expertise (MIT Press, 2010), p. 237.

A close reading of the sentence in question suggest that it is a highly qualified statement about contemporary perceptions, and not an absolute claim about percentages. But it since these percentages were so outside of the (at that time) contemporary wisdom about women in computing, it is worth breaking down the evidence I used to justify this sentence.

My immediate source in The Computer Boys for this claim was a 1974 report by the industry analyst Richard Canning. For more than a decade Canning published the influential EDP Analyzer newsletter, and often wrote about the growing labor market for computer programmers. In his 1974 discussion of “Issues in Programming Management,” Canning references Joel Aron, the General Manager of IBM Programming Systems Development, and says the following: “Aron says that about one-half of the programmers are women, and that the number of women managers is rising rapidly.”2Canning, Richard. 1974. “Issues in Programming Management.” EDP Analyzer 12 (4): 1–14. Canning, one of the most informed industry observer of the era, repeats this claim without comment or skepticism.

Canning’s source for the Aron quote is actually another contemporary report from the industry journal Infotech. A year previously, Infotech had published a massive 526 page report on “Computing Manpower” that included presentations and invited papers from eighteen industry leaders. The 50% estimate actually appears in this volume three times. The first is in the report from Joel Aron quoted by Canning, of which the relevant sentences are:

Of the programmers, about half are female; and the number of female managers is rising rapidly. At one time, when I had a line management division in the organization, two of the five key managers were women and, under them, about a third of the managers were women. Our experience, which I imagine is fairly typical, is that there is absolutely no difference in the performance of men and women in similar jobs.3Aron, Joel. 1973. “Manpower Control in Large Computer Projects.” In Computing Manpower : International Computer State of the Art Report, edited by C. Bunyan, 327–47. Maidenhead: Infotech Information Ltd.

While it is perhaps not necessary to defend the knowledge and experience of an IBM Vice President who had been with the company since 1954 and who was, in addition to having been the manager of several large software development groups at IBM, also the head of the IBM FSC Programming Laboratory and the editor-in-chief IBM sponsored Systems Programming Series (published by Addison-Wesley through at least the early 1980s), there is an earlier reference to the 50% figure. In a 1964 article in the NY Times entitled “Computers Are Getting Ideas From Women: I.B.M. the Leader in Employing Girls as Programers,” Vartanig Vartan suggests that 1200 out of IBM’s 2500 computer programmers were women. 1200/2500 is not quite 50%, but as Joel Aron might argue, close enough for Federal Systems work…

The second reference to a 50% figure in the Infotech report comes from a report by Suzette Harold on “The Role of Women in Computing.” The specific quote is from page 199 of the report, and reads:

Many installations now have more than 50% of women in their programming teams and indeed, commercial programming is in danger of becoming another “women’s job.” I say “in danger” because employers in the past have seen in women a source of cheap labor and once women are segregated into what thereafter becomes known as women’s jobs, equal pay and conditions are inhibited.4Harold, Suzette M. 1973. “The Role of Women in Computing.” In Computing Manpower : International Computer State of the Art Report, edited by C. Bunyan, 195–215. Maidenhead: Infotech Information Ltd.

Like Joel Aron, Suzette Harold was well-situated to comment on the role of women in computing. Harold served on the Council of Software Houses Association, a U.K.-based software industry organization. She had previously worked on software development at the Atomic Energy Research Establishment, the Rutherford High Energy Laboratory, and the Atlas Computer Laboratory. She was on the scientific staff at the Science Research Council. Like Aron, she had broad experience in the industry.

At the time she presented her findings on women in computing in the 1973 Infotech report, Harold was an executive at F International, which was a software services consulting firm that eventually would become a multi-million dollar firm with hundreds of clients spanning both the U.K. and the European continent. F International employed almost exclusively female programmers.

F International was not the only early software development company to take advantage of the large number of women working in computing in this period. It was itself a subsidiary of Freelance Programmers, a company founded in 1962 by Stephanie “Steve” Shirley. Freelance Programmers was one of the first consulting software development firms, and one of the most successful. When by-then-Dame Stephanie Shirley sold the company in 2007, it was worth £400 million. In 1962, when Freelance Programmers was helping to establish the software industry, it employed only women programmers. It only hired its first male programmers in 1975 when, ironically, it was forced to by the passage of Sex Discrimination Act in the UK. At that point there were 300 women working as programmers at Freelance. So, in 1962 we have a company in which the actual, well-documented percentage of female programmers is 100%.5Shirley, Stephanie, and Richard Askwith. 2013. Let It Go: The Story of the Entrepreneur Turned Ardent Philanthropist.

The third reference to 50% figure in the Infotech report is by the editor of the report C.J. Bunyan, who in his lengthy (150 page) introduction/summary to the report highlights both Aron and Harold’s assessments. Bunyan, who edited and authored numerous industry reports from this period, seemingly found nothing to disagree with in these estimates.

Although I do not cite them in The Computer Boys, there are other references to the 50% figure outside of the Infotech report. A 1964 article in the Guardian by Maureen Eppstein argued that 50% of programmers in the UK were women.6Eppstein, Maureen. 1964. “The Computer Women.” Guardian, January 31, 1964. I first discovered this reference in Janet Abbate’s 2012 book Recoding Gender, which is based on both historical research and a series of fifty-two oral histories she conducted with women who had worked as programmers in both the US and UK in the early decades of computing.7Abbate, Janet. 2012. Recoding Gender: Women’s Changing Participation in Computing. History of Computing. London, England: MIT Press. On the very first page of the first chapter of that book, Abbate quotes Paula Hawthorn, who worked as a programmer at Texaco in the mid-1906s. According to Hawthorn,

It never occurred to us that computer programming would eventually become something that was thought of as a men’s field. At that time … it was at least half women.8Abbate, p. 1

Note here both the (again, contemporary to the late 1960s) claim that 50% of all programmers were women and Hawthorn’s expressed surprise at her realization that programming was anything other than women’s work.

I should note that Janet Abbate herself does not endorse Hawthorn’s claim as being a true reflection of the actual percentage of women in computing in this period. To the degree that she even attempts to provide numerical estimates, she follows the Bureau of Labor Statistics numbers from the early 1970s.

But Hawthorn is not the only woman cited by Abbate who clearly believed that the percentage of programmers in the 1950s who were women was significant. As Elsie Shutt, another pioneering innovator in the software development consulting industry expressed in her interview with Abbate,

It really amazed me that these men were programmers, because I though it was women’s work.”

In this quote Shutt appears to be talking about her time as a programmer at Raytheon in the early 1950s. By 1957, Shutt had been forced to leave the company because she had gotten pregnant, and had founded Computations, Inc., which like Freelance Programmers employed 100% women. Shutt ran her company successfully for more than four decades. As far as I know, none of the employment records that would definitely document this claim remain in existence, but this is typical of the corporate records of smaller companies, and see no reason to doubt Schutt’s assessment of the state of the programming industry in the era that she helped define it.

And so we see that there are multiple, plausible claims from the 1960s that the percentage of computer programmers who were women was as high as (or even more than) 50%. There are also lower estimates. In a 1966 study of programming proficiency, Raymond Berger and Robert Wilson of the Electronic Personnel Research Group at the University of Southern California identified 28% of the 366 government civil service programmers as being women.9Berger, Raymond M., and Robert C. Wilson. 1966. “Correlates of Programmer Proficiency.” In Proceedings of the Fourth SIGCPR Conference on Computer Personnel Research – SIGCPR ’66. New York, New York, USA: ACM Press. This is the source I relied on for my lower abound of roughly 30%. Of course, without knowing exactly how Berger and Wilson selected their sample, it is uncertain how well representative their data represents the industry as a whole, but that is the best data I had to go on at the time, and their report was published in the Association for Computing Machinery (ACM) SIGCPR (Special Interest Group in Computer Personnel Research), the most relevant and prestigious professional publication in this area. When I was researching The Computer Boys, it was not as easy to access historical materials as it is today. And even if it had been, there are simply not many sources of reliable, quantified data from the 1950s and 1960s.

The first official government statistics on programmer employment comes from 1956 report by the US Labor Department on “Employment Opportunities for Women Mathematicians and Statisticians.” “It was a fact,” according to this report, “that many industrial laboratories employed only women in their computing groups; others employ a high percentage of women.” (from Abbate, 65, emphasis mine) The focus of this study on college-educated mathematicians and statisticians seems to suggest that it is talking about higher-level computing occupations such as programming and systems analysis, but it is also true that the term “computing group” potentially covers a variety of types of work, some of which were almost exclusively feminized (such as key-punch operator, or the now obsolete category of “computer operator”), and none of which we would today consider to be aspects of computer programming. That being said, the report also cites specifically one example of a laboratory in which “67% of the programming staff were women.”

The United States Bureau of Labor Statistics did not begin tracking programmer labor until 1970, and their estimate of the percentage of women in computing was 23%. As I (and others) have argued elsewhere, there are numerous reasons to believe that their data under-represents the number of women working as programmers (and, for that matter, the number of men)10See Ensmenger, The Computer Boys Take Over, as well as Loseke, Donileen R., and John A. Sonquist. 1979. “The Computer Worker in the Labor Force: New Occupations and Old Problems.” Sociology of Work and Occupations 6 (2): 156–83; Greenbaum, Joan. 1976. “Division of Labor in the Computer Field.” Monthly Review 28 (3): 40.Kraft, Philip, and Steven Dubnoff. 1986. “Job Control, Fragmentation, and Control in Computer Software Work.” Industrial Relations 2 (25). Bruce Gilchrist, who wrote extensively about labor issues in the computer industry and who held executive positions both in the Association for Computing Machinery (ACM) and the International Federation of Information Processing Societies (IFIPS), reviewed the 1970 BLS report and noted that the BLS numbers were significantly lower than earlier industry estimates.11Gilchrist, Bruce, and Richard E. Weber. 1974. “Enumerating Full-Time Programmers.” Communications of the ACM 17 (10): 592–93. Even prior to its publication, he had criticized the BLS report as being “based on relatively little firm data” and noted particularly the “lack of widely accepted standard definitions for occupations such as programmer, systems analyst, computer operator, etc.”12Gilchrist. 1969. “Manpower Statistics in the Information Processing Field.” Computers & Automation. These fundamental ambiguities, combined with a reliance on self-reporting and the tendency of some workers to inflate their job titles, meant that some forms of work systematically misrepresented. He notes particularly errors in the categorization of keypunch operators and computer operators, which were roles particularly associated with women.13Weber, Richard E., and Bruce Gilchrist. 1975. “Discrimination in the Employment of Women in the Computer Industry.” Communications of the ACM 18 (7): 416–18.

Over the course of the 1970s, Gilchrist and his co-author Richard Weber attempted to develop a better data set on programmer employment, consistently arguing that the BLS data was insufficient. But even as they developed alternative and more inclusive measures of programming labor, they acknowledged that their own data sources also under-represented the “significant and probably growing amount of programming” that we being performed by people and organizations who were not fully visible in the formal statistics.14Weber, and Gilchrist. 1972. “Employment of Trained Computer Personnel: A Quantitative Survey.” Communications of the ACM. Often they relied on a different data set from the BLS Area Wage Studies which excluded, among other groups, employees of educational institutions, scientific programmers, agricultural employees, and the self-employed. As far as I am aware, Gilchrist and Weber make only one attempt to estimate the percentage of female programmers, and they highly qualify this in the same way that they do all of their estimates. In that study, their figure of 21% corresponds closely to the BLS statistic.15Weber, Richard E., and Bruce Gilchrist. 1975. “Discrimination in the Employment of Women in the Computer Industry.” Communications of the ACM 18 (7): 416–18. But as they point out in their 1974 attempt at “Enumerating Full Time Programmers,” the lack of standard categories and structural biases in the data meant that, at best, they could “paint only a hazy and incomplete picture of the employment situation in computer related occupations.”16Gilchrist, Bruce, and Richard E. Weber. 1974. “Enumerating Full-Time Programmers.” Communications of the ACM 17 (10): 592–93.

The fact that even basic terms like “software” and “programming” were being actively defined and negotiated during the 1950s makes it difficult to rely on job titles or self-descriptions of work. Consider the female operators of the ENIAC, the so-called “ENIAC Girls” (the use of such gendered language, while unpalatable to modern sensibilities, is essential to understanding the gender dynamics of early computing): as both Janet Abbate and Thomas Haigh have correctly noted, both “coder” and “programmer” are anachronisms when applied to the work these women did. Such concepts and categories did exist at the time. And yet the work these women did undeniably helped shape the practices that would become programming, and many of them would go on to work in roles that would become labeled as “programmer.” And they most definitely saw themselves as pioneering programmers.17Bartik, Jean, Jon T. Rickman, and Kim D. Todd. 2013. Pioneer Programmer. Truman State University Press. Do we count them as programmers? I would, but I can also see the argument for not doing so. If we do consider them to be computer programmers, than for that brief moment in history, at that particular (but highly visible and influential) place, the percentage of programmers who were women was 100%. As we have seen, much depends on which moment and which organization one chooses as a representative snapshot.

All this being said, the “between 30-50%” figure so often cited from The Computer Boys was never meant to be a definitive estimate of the percentage of working programmers who were women. In my research I generally resist trying to precisely enumerate the number of computer programmers (male or female) working in the period covered by the book (which is roughly 1946-1968). In fact, a key argument of the book is that it would be almost entirely pointless to even attempt to do so, since this is the period during which the very categories of what constituted “computer work” were being actively negotiated. Who “counted” as a computer worker was a highly contested question. Much of the scientific and informational work that today we associate with computers did not originate with computing (data processing was a well-established industry long before the advent of electronic computing, and IBM was a globally dominant information technology company decades before it manufactured its first computer), and many of those who happened to use computers in their work still identified primarily as engineers, scientists, systems analysts, or professional managers. Not only were there no industry-standard job categories for computer work in this period, practitioners themselves used a variety of terms to describe what they did and who they were. Trying to be too precise about the total number of “computer workers” would be a pointless exercise, and in my written work I try to be careful to avoid doing so. In fact, I embrace this ambiguity, in large part because I believe is more authentic to the experience of my historical actors. But that computer programming was seen in the 1950s and 1960s as uniquely accessible to women — in stark contrast to later periods —is undeniable. (For more on my historical work on gender and computing, see the posts YOUR CAREER IN COMPUTER PROGRAMMING and THE COMPUTER GIRLS? as well as my articles “‘Beards, Sandals, and Other Signs of Rugged Individualism’: Masculine Culture within the Computing Professions“18Ensmenger, Nathan. 2015. “‘Beards, Sandals, and Other Signs of Rugged Individualism’: Masculine Culture within the Computing Professions.” Osiris 30 (1): 38–65. and “Making Programming Masculine.”19Ensmenger, Nathan. 2010. “Making Programming Masculine.” In Gender Codes: Why Women Are Leaving Computing. ). See also the work of Janet Abbate and Mar Hicks, among others.

  • 1
    Ensmenger, The Computer Boys Take Over: Computers, Programmers, and the Politics of Technical Expertise (MIT Press, 2010), p. 237. ↩︎
  • 2
    Canning, Richard. 1974. “Issues in Programming Management.” EDP Analyzer 12 (4): 1–14. ↩︎
  • 3
    Aron, Joel. 1973. “Manpower Control in Large Computer Projects.” In Computing Manpower : International Computer State of the Art Report, edited by C. Bunyan, 327–47. Maidenhead: Infotech Information Ltd. ↩︎
  • 4
    Harold, Suzette M. 1973. “The Role of Women in Computing.” In Computing Manpower : International Computer State of the Art Report, edited by C. Bunyan, 195–215. Maidenhead: Infotech Information Ltd. ↩︎
  • 5
    Shirley, Stephanie, and Richard Askwith. 2013. Let It Go: The Story of the Entrepreneur Turned Ardent Philanthropist. ↩︎
  • 6
    Eppstein, Maureen. 1964. “The Computer Women.” Guardian, January 31, 1964. ↩︎
  • 7
    Abbate, Janet. 2012. Recoding Gender: Women’s Changing Participation in Computing. History of Computing. London, England: MIT Press. ↩︎
  • 8
    Abbate, p. 1 ↩︎
  • 9
    Berger, Raymond M., and Robert C. Wilson. 1966. “Correlates of Programmer Proficiency.” In Proceedings of the Fourth SIGCPR Conference on Computer Personnel Research – SIGCPR ’66. New York, New York, USA: ACM Press. ↩︎
  • 10
    See Ensmenger, The Computer Boys Take Over, as well as Loseke, Donileen R., and John A. Sonquist. 1979. “The Computer Worker in the Labor Force: New Occupations and Old Problems.” Sociology of Work and Occupations 6 (2): 156–83; Greenbaum, Joan. 1976. “Division of Labor in the Computer Field.” Monthly Review 28 (3): 40.Kraft, Philip, and Steven Dubnoff. 1986. “Job Control, Fragmentation, and Control in Computer Software Work.” Industrial Relations 2 (25). ↩︎
  • 11
    Gilchrist, Bruce, and Richard E. Weber. 1974. “Enumerating Full-Time Programmers.” Communications of the ACM 17 (10): 592–93. ↩︎
  • 12
    Gilchrist. 1969. “Manpower Statistics in the Information Processing Field.” Computers & Automation. ↩︎
  • 13
    Weber, Richard E., and Bruce Gilchrist. 1975. “Discrimination in the Employment of Women in the Computer Industry.” Communications of the ACM 18 (7): 416–18. ↩︎
  • 14
    Weber, and Gilchrist. 1972. “Employment of Trained Computer Personnel: A Quantitative Survey.” Communications of the ACM. ↩︎
  • 15
    Weber, Richard E., and Bruce Gilchrist. 1975. “Discrimination in the Employment of Women in the Computer Industry.” Communications of the ACM 18 (7): 416–18. ↩︎
  • 16
    Gilchrist, Bruce, and Richard E. Weber. 1974. “Enumerating Full-Time Programmers.” Communications of the ACM 17 (10): 592–93. ↩︎
  • 17
    Bartik, Jean, Jon T. Rickman, and Kim D. Todd. 2013. Pioneer Programmer. Truman State University Press. ↩︎
  • 18
    Ensmenger, Nathan. 2015. “‘Beards, Sandals, and Other Signs of Rugged Individualism’: Masculine Culture within the Computing Professions.” Osiris 30 (1): 38–65. ↩︎
  • 19
    Ensmenger, Nathan. 2010. “Making Programming Masculine.” In Gender Codes: Why Women Are Leaving Computing. ↩︎

Black Programmers

In celebration of Black History Month, I have been reflecting on what my scholarship might have to say about the history of African American computer programmers. I have posted previously about race, class, and gender in history of computing, but that was many years ago, and there have been some exciting developments in the literature in the past few years.

When I was writing The Computer Boys, there was almost no literature available on the intersection of race and computing. Nor was there much data to be found in the primary sources.

In their analysis of data the 1970 Census and the Department of Labor’s Area Wage Surveys, Bruce Gilchrist and Richard Weber suggested that out of a total of 161,337 working programmers in the United States, 5,837 (3.6%) were African American. Of male programmers (124,956 total), just 3.2% (4,008) were African American. Of female programmers (36,381 total), slightly more than 5% (1,829) were women.1Bruce Gilchrist and Richard Weber, “Enumerating Full-Time P Communications of the ACM 17, no. 10 (1974): 592–593.

The 1970 Census data also tracked programmer’s of “Spanish heritage”. There were 2,957 male programmers and 602 female programmers in this category.

I have already written about why I think the official numbers underestimate the total number of working programmers. Given the fluidity and limitations of racial categories in Census data in this period, I have similar concerns about this data.

In addition to purely quantitative data, there were indications in my historical sources of not only the contributions of African Americans, but to some interesting questions related to race and computing. For example, in the late 1960s, during a time a particularly visible and violent racial strife, there were several attempts to provide programmer training to black communities. But while some of these were legitimate (and a few were government-sponsored) there were also a number of exploitative vocational schools that preyed on Black communities. In Chapter 3 (“Chess Players, Music Lovers, and Mathematicians”) of the book I write about the larger phenomenon of these schools and their problematic reputation within the industry.

Update: the artist ann haeyoung is developing an oral history project on the IBM Black Workers Alliance that overlaps with the period I cover in book. This is a fascinating project! I had no idea this group existed.

Since The Computer Boys was published, there are a number of histories of Black programmers that have been written. The most prominent of these is Margot Shetterly’s 2016 book Hidden Figures (dramatized in the film, also from 2016), which tells the stories of some of the African American women who worked as “human computers” and programmers in the space program.2Shetterly, Margot Lee. 2016. Hidden Figures: The Untold Story of the African American Women Who Helped Win the Space Race. HarperCollins The film in particular focused on just three of these (Dorothy Vaughan, Mary Jackson, Katherine Johnson), but there were many others: Christine Darden, Annie Easley, Melba Roy Mouton, Jeanette A. Scissum, to name just a few.3See for example Jade Reyerson, “Places of Hidden Figures: Black Women Mathematicians in Aeronautics and the Space Race,” National Park Services. https://www.nps.gov/articles/000/places-of-hidden-figures.htm

One of the earliest scholarly discussions of race and computing in the scholarly literature is Arvid Nelson’s “Race and Computing: The Problem of Sources, the Potential of Prosopography, and the Lesson of Ebony Magazine,” which was published in 2017 in the IEEE Annals of the History of Computing.4Nelsen, R. Arvid. 2017. “Race and Computing: The Problem of Sources, the Potential of Prosopography, and the Lesson of Ebony Magazine.” IEEE Annals of the History of Computing 39 (1): 29–51. I was editor-in-chief of the Annals at that point, and so can say definitively that in the almost four decades that that journal served the journal of record for the history of computing community, that was the first article that explicitly addressed the historiography of race and computing.

More recently, there are a number of scholarly articles and books that deal with questions of race and computing. A few of these are historical, although most deal with more contemporary issues. Here are a few that focus specifically on the African American experience.

Eglash, Ron. 2002. “Race, Sex, and Nerds: From Black Geeks to Asian American Hipsters.” Social Text 2 (20): 49–64.

Browne, Simone. 2015. Dark Matters: On the Surveillance of Blackness.

Shetterly, Margot Lee. 2016. Hidden Figures: The Untold Story of the African American Women Who Helped Win the Space Race. HarperCollins

Williams, Jeannette, Yolande Dickerson, The Invisible Cryptologists: African-Americans, WWII to 1956. United States, National Security Agency/Central Security Service, and Center for Cryptologic History. 2001.

Noble, Safiya Umoja. 2018. Algorithms of Oppression: How Search Engines Reinforce Racism.

Brock, André L. 2019. Distributed Blackness: African American Cybercultures.

Benjamin, Ruha. 2019. Race after Technology: Abolitionist Tools for the New Jim Code. Cambridge: Polity.

McIlwain, Charlton D. 2020. Black Software: The Internet and Racial Justice, from the AfroNet to Black Lives Matter.

Katz, Yarden. 2020. Artificial Whiteness: Politics and Ideology in Artificial Intelligence. Columbia University Press.

Also, since African American inventiveness is not a recent phenomenon, here are a few classics from the history of technology

James, Portia P., and Anacostia Neighborhood Museum. 1990. The Real McCoy: African-American Invention and Innovation, 1619-1930. Washington, D.C.: Published for the Anacostia Museum of the Smithsonian Institution by the Smithsonian Institution Press.

Fouché, Rayvon. 2005. Black Inventors in the Age of Segregation: Granville T. Woods, Lewis H. Latimer, and Shelby J. Davidson. JHU Press.

Sinclair, Bruce, and Massachusetts Institute of Technology. 2004. Technology and the African-American Experience: Needs and Opportunities for Study. Cambridge, Mass.: Massachusetts Institute of Technology.

Green, Venus. 2001. Race on the Line: Gender, Labor, and Technology in the Bell System, 1880-1980. Durham: Duke Univ. Press.

  • 1
    Bruce Gilchrist and Richard Weber, “Enumerating Full-Time P Communications of the ACM 17, no. 10 (1974): 592–593. ↩︎
  • 2
    Shetterly, Margot Lee. 2016. Hidden Figures: The Untold Story of the African American Women Who Helped Win the Space Race. HarperCollins ↩︎
  • 3
    See for example Jade Reyerson, “Places of Hidden Figures: Black Women Mathematicians in Aeronautics and the Space Race,” National Park Services. https://www.nps.gov/articles/000/places-of-hidden-figures.htm ↩︎
  • 4
    Nelsen, R. Arvid. 2017. “Race and Computing: The Problem of Sources, the Potential of Prosopography, and the Lesson of Ebony Magazine.” IEEE Annals of the History of Computing 39 (1): 29–51. ↩︎

Computers, Programmers, and the Politics of Technical Expertise